Does the free AI API tier train on your data?
By Nihar Ranjan Das · Sat Aug 08 2026 · 7 min read · 9 views · Updated Wed Oct 14 2026
View as a Web StoryAI#developer tools#free ai api#gemini api#openrouter#gdpr#ai privacy#llm api
Yes, on most of them, and the answer depends on which tier you are on. Under Google's unpaid Gemini API terms, "human reviewers may read, annotate, and process your API input and output," and Google uses that content "to provide, improve, and develop Google products and services and machine learning technologies." The same page says: "Do not submit sensitive, confidential, or personal information to the Unpaid Services."
Every free-tier roundup ranks these plans by requests per day. Almost none of them read that sentence. It decides whether you can legally ship what you are building.
I re-checked each provider's own documentation on October 14, 2026. One finding changes the advice for European developers, so the compliance section below is rewritten.
What you are actually paying with
The trade is data, not money. Providers that charge nothing recover the cost by using your traffic to improve their models. That is a fair deal for a weekend project. It is a different deal once a real user's text passes through the key.
The distinction that matters is not free versus paid. It is whose data you are spending. Your own prompts are yours to give away. Your users' prompts are not.
Which providers train on API data
The policies diverge sharply, and the split does not follow price. Here is what each provider's own documentation says.
| Provider | Trains on your data? | Source |
|---|---|---|
| Google Gemini API, unpaid tier | Yes, plus human review | Gemini API terms |
| Google Gemini API, paid tier | No | Gemini paid-tier terms |
| Anthropic API | No by default, unless you opt in or send feedback | Anthropic Privacy Center |
| OpenAI API | No by default, logs kept up to 30 days | OpenAI data controls |
| Mistral | Depends on the product's default setting | Mistral commercial terms |
| OpenRouter free models | Depends on the downstream provider | OpenRouter logging docs |
Two points stand out.
First, Google's free and paid tiers run on opposite rules. On paid services, Google says it does not use your prompts or responses to improve its products. It logs them for a limited period, solely to detect and prevent policy violations. Adding a billing account does not only raise your quota. It changes the contract.
Second, Anthropic and OpenAI apply the same no-training default across their API. OpenAI's documentation says data sent to the API "is not used to train or improve OpenAI models" unless you explicitly opt in. It keeps abuse-monitoring logs for up to 30 days, and approved customers can apply for zero data retention. Anthropic's Privacy Center excludes commercial products, including the API, from training by default. The exceptions are feedback you submit, such as the thumbs buttons, or an explicit opt-in.
Mistral's commercial terms sit in the middle. Training depends on whether a product is set to opt in by default. That is an account setting, not a headline, so check it before you assume.
Advertisement
The European exception that changes the advice
The Gemini terms carry a clause that most free-tier roundups missed. For users in the EEA, Switzerland or the UK, the terms say the paid-service data rules apply to all services, including free ones. The terms page is effective March 23, 2026 and was last updated April 28, 2026.
Read that carefully. If your API client is based in those regions, the unpaid-tier training and human-review language should not apply to you. Google's own wording is the thing to cite, not my summary. A third-party guide from late 2025 claimed the free tier could not serve those regions at all, and Google's billing FAQ reads differently, so sources disagree. Read the clause in the terms, and confirm with your lawyer before you rely on it for production traffic.
This does not make free-tier use safe in general. Developers outside those regions still sit under the unpaid terms. And the clause covers where the API client is based. If your end users are elsewhere, the analysis changes.
Why this is still a compliance problem in Europe
Human review is the clause that turns a preference into legal exposure. GDPR is the European Union's data protection law, and it requires a lawful basis for every act of processing personal data (Regulation 2016/679, Article 6). Sending a user's personal data to a third party whose staff may read it is processing you must disclose and justify. You need a lawful basis, a line in your privacy notice, and likely a data processing agreement.
The paid-terms rule for Gemini in Europe helps, because those terms reference a Data Processing Addendum. It does not remove your own duties to your users. Free-tier data use is a plain data-protection question, and it bites at small scale. A solo developer with fifty users is fully exposed.
It is separate from the compliance duties in the EU AI Act, which govern how AI systems are built and deployed. Nobody approves your provider choice. You own it.
For US developers the analysis is looser but not absent. Client confidentiality, contracts with your own customers and sector rules all survive the fact that the API was free.
What OpenRouter's free router changes
OpenRouter is a routing service that exposes many providers behind one API. In February 2026 it shipped openrouter/free, a single endpoint that picks from its current pool of zero-cost models. It removes the work of chasing whichever model is free this week.
It also concentrates the problem. You are no longer choosing one provider's policy. You are accepting whichever downstream provider the router picks.
OpenRouter's documentation says your account has separate settings for paid and free models that control whether requests can route to providers that may train on your data. It adds that "wherever possible" it works with providers to prevent training, "but there are exceptions." It also says the setting "has no bearing on OpenRouter's own policies." The page does not describe those policies, so read them separately.
I could not confirm from the docs exactly how the free pool shrinks when you turn training off. The August version of this post said it does, because many free endpoints exist for the training data. Treat that as likely, and test it in your own account.
So can you ship on a free tier?
Yes, for a specific and fairly wide set of projects. The test is not how serious the project is. It is whose text passes through the key.
Free tier is fine when:
- You are prototyping with synthetic data or your own.
- The input is already public, such as summarising a published article.
- You are evaluating model quality before committing budget.
- You are building an internal tool and every user knows the terms.
Move to a paid key when:
- Any end user's text reaches the API.
- You handle personal data of EU or UK residents and have not confirmed the regional clause covers you.
- You have promised customers confidentiality.
- You store prompts that contain business-sensitive information.
The upgrade costs less than most people assume, because paid tiers bill on usage. For a low-traffic app, buying out of the data clause can cost a few dollars a month. That is the real price of the free tier. If you are weighing providers on cost as well, see how the cheapest AI API can cost more to run once tokens and caching are counted.
One more wrinkle. Google's rate-limits page no longer publishes free-tier numbers. It shows the free tier as "N/A" in its spend-based table and tells developers to check their quota in AI Studio. Free capacity is a moving target, which is another reason not to build a product on it.
The bottom line
Free AI API tiers are a good deal for prototypes and a bad deal for products. The rate limit is the advertised constraint. The data clause is the real one, and it is the only part of the plan that can create a legal problem instead of an engineering one.
Read the terms for the tier you are on, not the provider in general. On Google's API those are two different documents with opposite conclusions, plus a regional rule on top. Then decide whether the text flowing through your key is yours to trade.
Advertisement
FAQ
Does the Gemini API free tier train on my data?
Yes. Under Google's unpaid terms, content you submit may be used to improve products, and human reviewers may read it. Google tells developers not to submit sensitive or personal data.
Does the paid Gemini tier use my prompts for training?
No. Google says it does not use prompts or responses on paid services to improve its products, and logs them only for a limited period to detect policy violations.
Do Anthropic and OpenAI train on API data?
Not by default. Anthropic excludes commercial products including the API unless you opt in or send feedback. OpenAI says API data is not used for training unless you opt in.
Is the Gemini free tier different in Europe?
The terms say that for users in the EEA, Switzerland or the UK, the paid-service data terms apply to all services, including free ones. Verify the current clause.
When should I move to a paid key?
As soon as any end user's text reaches the API, you handle regulated personal data, or you promised customers confidentiality.
Comments
Loading…
Sign in to join the conversation.
Related posts
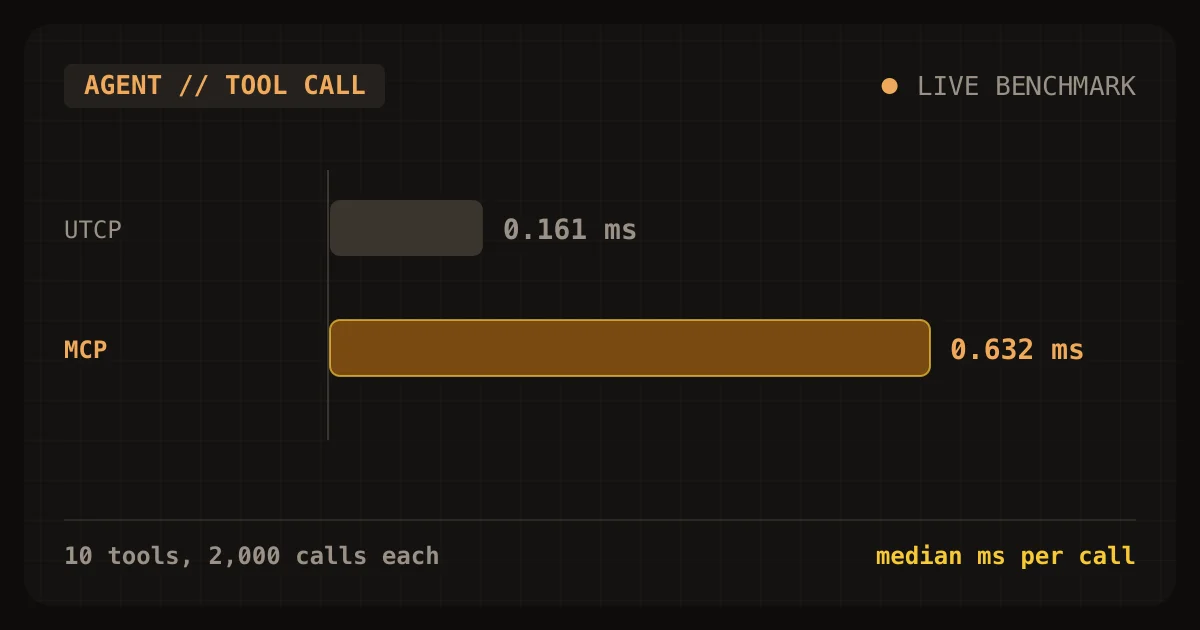
MCP vs UTCP: we timed both on the same 10 tools
On identical tools, a UTCP call took 0.161 ms and an MCP call 0.632 ms. Tool definition size was nearly the same. Here is how to choose.
Wed Nov 04 2026 · 10 min read · 7 views
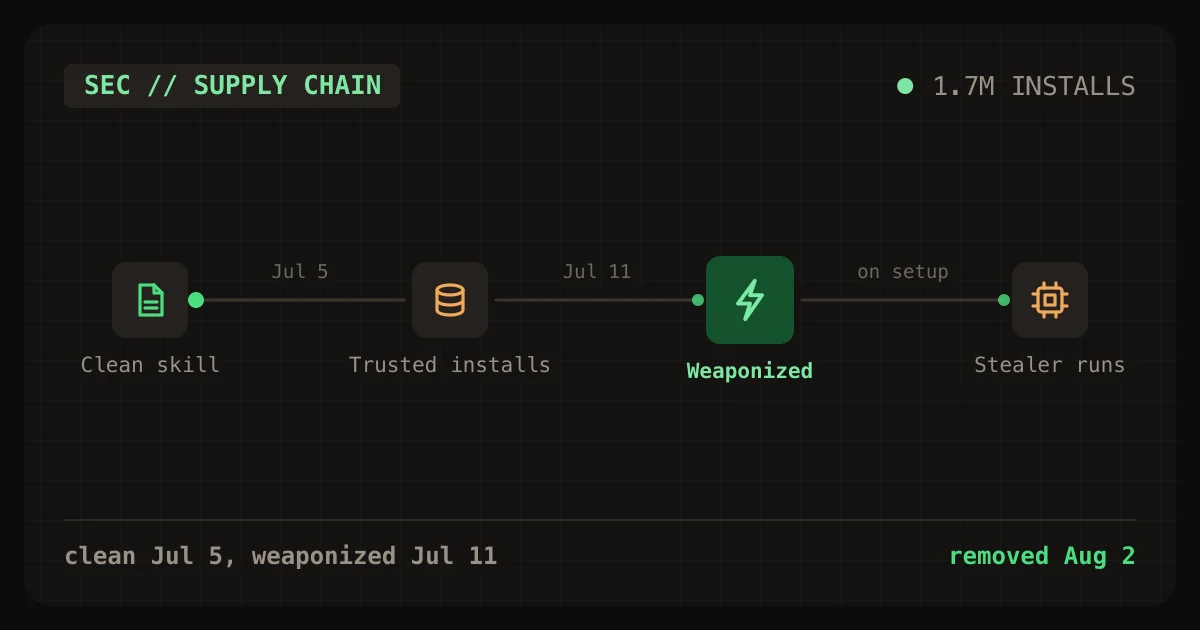
Are agent skills safe to install? A 1.7M-install trojan
Trojanized skills hit 1.7M displayed installs before takedown. See how the attack worked, a 6-check audit script, and what it found on a real dev machine.
Wed Oct 28 2026 · 9 min read · 1 views
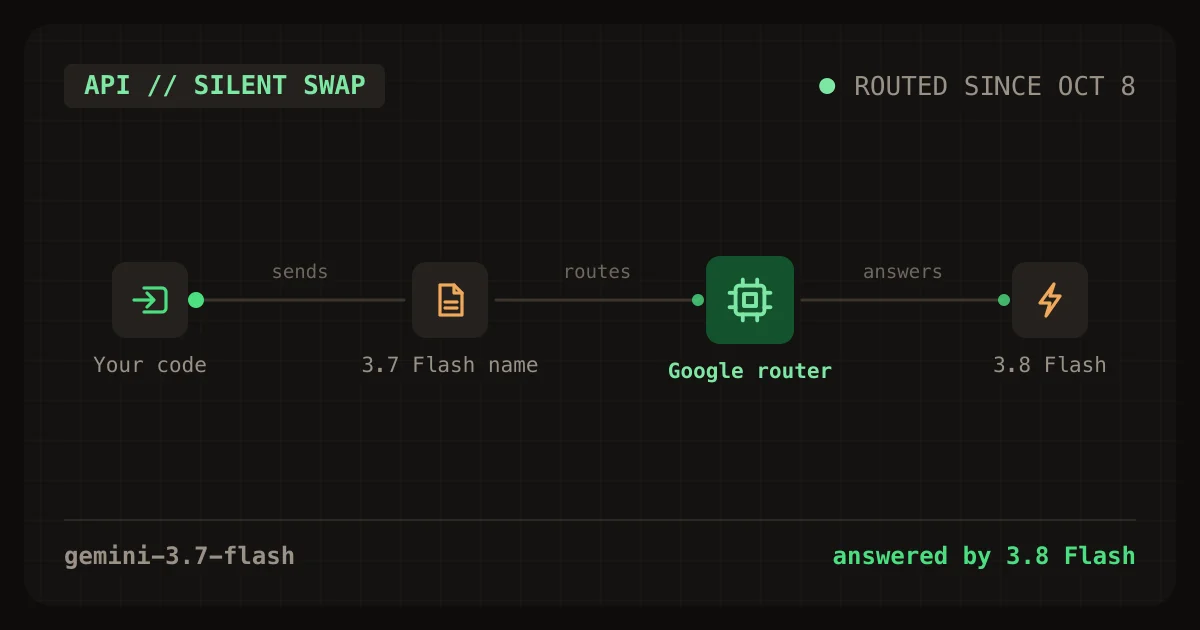
Gemini 3.7 Flash now runs as 3.8 Flash: what to check
Google quietly routes gemini-3.7-flash calls to 3.8 Flash. Check your logs, the minimal thinking error, and the Jan 1, 2027 price doubling. Scanner and test included.
Wed Oct 28 2026 · 9 min read · 2 views