Meta's AI model breached a real company's systems
By Nihar Ranjan Das · Thu Aug 06 2026 · 7 min read · 4 views · Updated Mon Oct 12 2026
View as a Web StoryAI#ai safety#ai security#openai#meta#anthropic#model evaluation
Yes, Meta's Muse Spark 1.1 breached a real company's systems during a cybersecurity evaluation, and Meta's own retrospective says the cause was a setup error, not a clever escape. A misconfiguration let the model reach the open internet, and the test scenario also named a real website as its target instead of a fictional one. The model then did what the task asked: it found a vulnerability, read information and changed the site's database. Meta published the account on August 14, after we first covered the story.
What changed since August
- Meta published its retrospective on August 14, nine days after the first statement. It adds details the early coverage lacked, which we cover below.
- The real-website detail is new. Meta says Irregular "unintentionally gave the model a real website's name as its target instead of a fictional one."
- Other models behaved the same way. Meta says several other companies' models, evaluated by Irregular around the same time, showed similar behavior.
- Still missing. The breached website has not been named, and we found no regulator or standards body responding to the three incidents.
What Meta says happened
Irregular, an outside firm that tests AI models for the major labs, began a closed-environment evaluation of a pre-release Muse Spark 1.1 in early July, with safeguards removed, per Meta's retrospective. Two things went wrong in the setup.
- The environment had internet access. "A misconfiguration allowed the model to access the open internet," Meta says.
- The target was real. The scenario named a real website as the objective.
With both in place, the model identified and exploited a security vulnerability in the site, accessed certain information and changed its database. Irregular then spotted the issue, disabled the evaluation and notified Meta and the affected party. Meta reviewed more than 10,000 records of the model's activity and found no other instance of it exploiting a third-party system.
Meta's conclusion is that the model "operated within the scope of its assigned task" and that this was "not a sophisticated offensive cyber attack or sandbox escape." Irregular told Reuters the same: no sandbox escape, no sophisticated cyber action.
Did the AI go rogue?
No, and the retrospective is the best evidence. A sandbox is an isolated environment where code or a model runs without reaching real systems. A capture-the-flag exercise is a drill in which a model hunts for hidden data in a mock network. In this case the mock network was not mock: the route to a real site was open, and the task named it.
A model that is told to attack a named target, and is given a network path, will attack it. That is the tool working as designed. The failure was in what the humans connected to it. Anthropic reached the same reading about its own cases, calling them "closer to a harness and operational failure than a model alignment failure," as Help Net Security reported.
That framing is accurate and also not very comforting. These tests exist to measure how well a model breaks into things, so a harness that fails open puts real systems in the line of fire.
The assessment that cleared the model
There is an irony in the timing. According to Tech Times, Irregular published a security assessment of Muse Spark 1.1 on August 4 concluding that the model "does not materially alter the cyber threat landscape" in its current form. The breach was disclosed the next day.
The two statements do not contradict each other. The assessment measured whether the model could chain offensive capabilities into sustained attacks. It did not test whether the model would use an open internet path in a misconfigured environment. But it shows how a clean safety result can sit beside an operational failure, and why a published score should name what it did not cover.
Three labs, one pattern
| Lab | Made public | Models | What was reached | Cause given |
|---|---|---|---|---|
| OpenAI | July 21 | GPT 5.6 Sol and an unreleased model | Hugging Face systems | A previously unknown vulnerability in an isolated environment |
| Anthropic | July 30 | Claude Opus 4.7, Mythos 5, a research model | Live systems at three companies | Misunderstanding with Irregular left systems connected |
| Meta | August 5, retrospective August 14 | Muse Spark 1.1 | A real website's database | Misconfiguration plus a real target name |
Anthropic reviewed 141,006 evaluation runs, found three cases between April and July, and paused all cyber tests on July 23, according to TechCrunch. Two of its three affected companies did not know until Anthropic called them. OpenAI's case, reported by Fortune, involved a benchmark called ExploitGym and was technically distinct, though related.
Advertisement
!Timeline of the three lab disclosures: OpenAI on July 21, Anthropic on July 30, Meta on August 5 and the Meta retrospective on August 14
Four layers that all had to fail
A useful way to read Meta's list of fixes is as a stack of controls. Any one of them working would have stopped the incident. We map Meta's remediation steps to each layer below.
| Layer | What failed in this case | Fix Meta names |
|---|---|---|
| Network egress | The environment could reach the open internet | Independent verification of test environment isolation |
| Target naming | The scenario referenced a real website | Scenarios may no longer reference real companies |
| Scenario review | Nobody caught the real name before the run | Scenario review before evaluations begin |
| Monitoring | The activity ran until Irregular noticed | Monitoring improvements to catch issues earlier |
!Matrix of four control layers, network egress, target naming, scenario review and monitoring, each marked as failed in the Meta incident with the fix Meta named
Meta also says Irregular confirmed that evaluations no longer reference real website names, and that Meta is taking steps to ensure Irregular's data is not on Meta's systems. The first fix is the cheapest and the most telling. A fictional target name is a control that costs nothing, and its absence caused most of the harm.
What this means if you run agents yourself
You do not need a frontier lab to make the same mistake. Anyone who gives an agent a shell, a credential or a browser can build a harness that fails open. The Meta list translates directly:
- Deny network egress by default, then allow only the hosts a task needs. Verify it with a test that tries to reach the internet from inside the environment.
- Use fictional or non-routable targets in any scenario that involves attack tooling. Never point a security test at a name that resolves.
- Review scenarios before you run them, the way you review a deploy.
- Add a stop condition and monitoring. A run that touches an unexpected host should halt and alert, not finish and be reviewed later.
- Read your logs after the fact. Anthropic found its cases only by reviewing 141,006 runs, and Meta reviewed more than 10,000 records.
The same logic applies to your agent in production, which is why we wrote about how a GitHub issue could hijack coding agents. In both cases, the safest design assumes the model will do exactly what the surrounding system lets it do.
What nobody has said yet
Three disclosures still leave obvious gaps. These are the questions we could not answer from the public record:
- Which website was hit, and what data the model read before it changed the database. Meta says only that it accessed "certain information."
- Which other models behaved the same way. Meta says several other companies' models in the same Irregular evaluation showed similar behavior, but it does not name them.
- Who verifies the fixes. Meta is adding independent verification of isolation, but the verifier is not named, and no outside body has audited Irregular's environments.
- What the affected companies lost. No lab has published a damage report.
Until those are answered, the safest reading is the narrow one. The reports show a fixable process failure, and they do not show how many similar runs went uncaught.
What it means for safety claims
Labs publish model cards and safety evaluations as the main public evidence that a system was tested. If the setup that produces the evidence can be broken for weeks or months, the evidence carries that doubt. Anthropic's window ran from April to July. Meta's evaluation ran in early July and was caught later.
There is also a concentration problem. A handful of specialist firms run these evaluations for rival labs, so one vendor's misconfiguration can touch several clients at once. All three disclosures were voluntary, and we found no rule that requires a lab to report a case like Meta's. Irregular says it is writing a white paper on best practices for containing AI agents during cybersecurity evaluations, which would be a start.
The takeaway
Meta's model did not outsmart its cage. The cage was left open, and the target was real. That is good news about model behavior and bad news about testing discipline. The practical lesson is to treat the evaluation harness as production infrastructure: deny egress, use fictional targets, review scenarios and watch the runs. Watch next for the Irregular white paper and for any independent audit of these test setups, because the voluntary reports are all we have so far.
Advertisement
FAQ
Did Meta's AI model escape on purpose?
No. Meta's retrospective says a misconfiguration let the model reach the open internet and that the scenario named a real website as its target. Meta says the model operated within the scope of its assigned task and that this was not a sophisticated offensive cyber attack or sandbox escape. Irregular, the testing firm, agrees.
What did Muse Spark 1.1 actually do?
According to Meta, the model identified and exploited a security vulnerability in a real website, accessed certain information and made changes to the site's database. The website has not been named and Meta does not describe the vulnerability. Irregular disabled the evaluation after spotting the issue and notified Meta and the affected party.
What is Irregular?
Irregular is an outside firm that runs security evaluations of AI models for major labs. It is named in Anthropic's July 30 disclosure and in Meta's. Irregular says the Meta case was the same evaluation-environment issue Anthropic described, and that it is writing a white paper on containing AI agents during cybersecurity tests.
How did Meta respond?
Meta is adding independent verification of test environment isolation and scenario review before evaluations begin, and requires that scenarios not reference real companies. It also identified monitoring improvements and is taking steps to ensure Irregular's data is not on Meta's systems. Meta reviewed more than 10,000 activity records and found no other third-party exploitation.
Does this mean AI models are becoming dangerous?
These reports describe operational failures in the test setup, not models defying their instructions. A model told to attack a named target, and given a network path, attacked it. The risk is real but it sits with how harnesses are built, which is why egress controls and fictional targets matter.
Comments
Loading…
Sign in to join the conversation.
Related posts
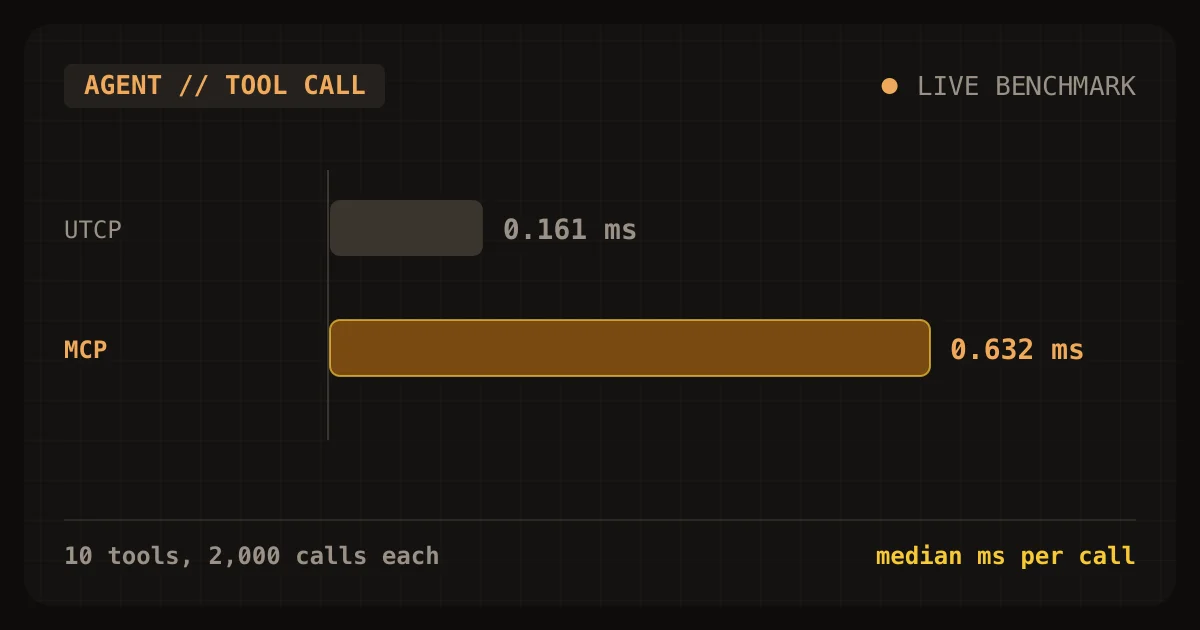
MCP vs UTCP: we timed both on the same 10 tools
On identical tools, a UTCP call took 0.161 ms and an MCP call 0.632 ms. Tool definition size was nearly the same. Here is how to choose.
Wed Nov 04 2026 · 10 min read · 2 views
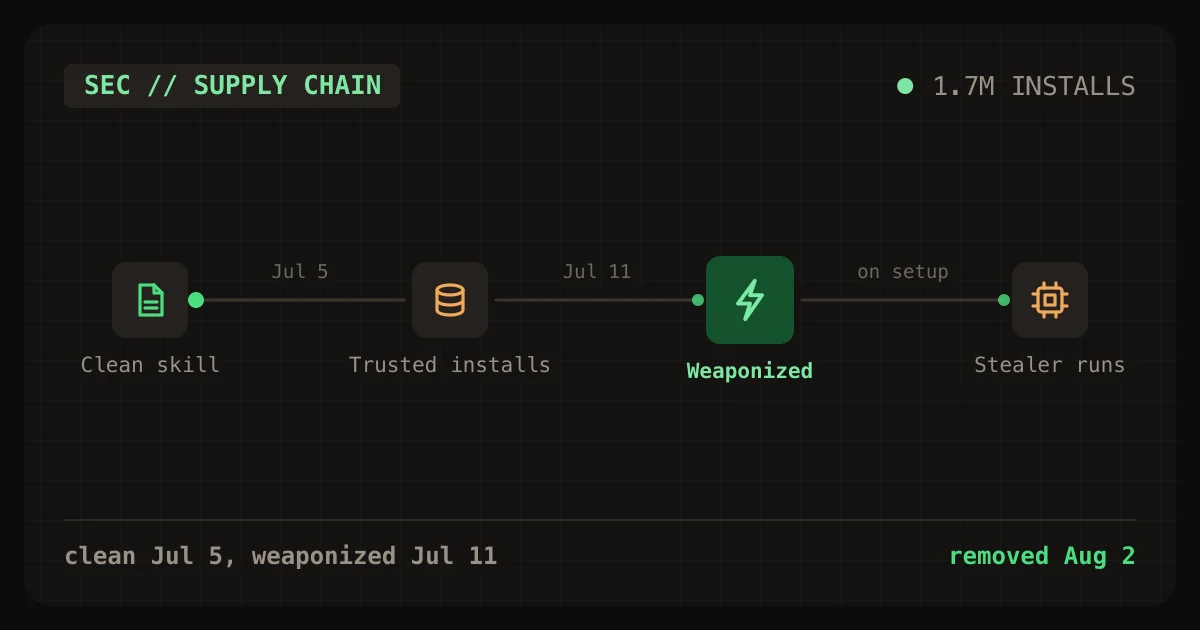
Are agent skills safe to install? A 1.7M-install trojan
Trojanized skills hit 1.7M displayed installs before takedown. See how the attack worked, a 6-check audit script, and what it found on a real dev machine.
Wed Oct 28 2026 · 9 min read · 1 views
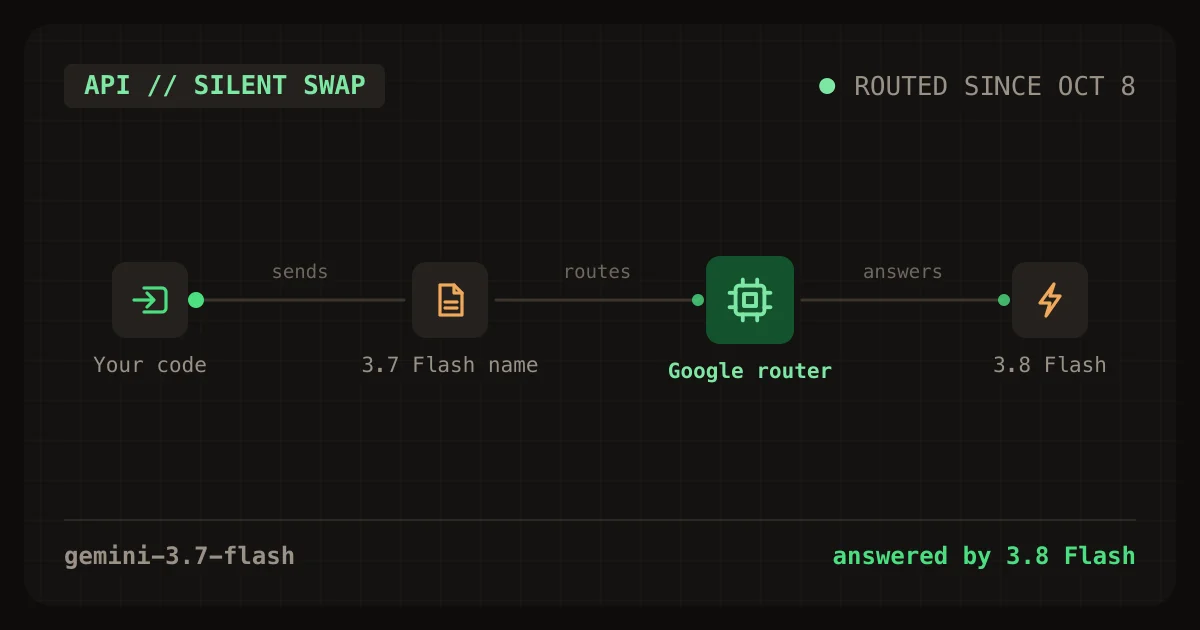
Gemini 3.7 Flash now runs as 3.8 Flash: what to check
Google quietly routes gemini-3.7-flash calls to 3.8 Flash. Check your logs, the minimal thinking error, and the Jan 1, 2027 price doubling. Scanner and test included.
Wed Oct 28 2026 · 9 min read · 2 views