What Is OpenAI Astra? A Model That Ships Math Proofs
By Nihar Ranjan Das · Mon Aug 03 2026 · 8 min read · 8 views · Updated Mon Oct 12 2026
View as a Web StoryAI#openai astra#lean 4#ai math#formal verification#gpt-6
OpenAI Astra is the name of OpenAI's next major model family, and as of October 12, 2026 it is still unreleased, with no date and no confirmed version name. What the world has instead is proof. On August 1 OpenAI published ten math results with Lean 4 proofs that anyone can compile, and on October 6 it released a far larger collection. That second release has already produced a useful lesson: three papers were withdrawn after OpenAI found a sign error, which is exactly the kind of failure a formal proof catches and an unformalized one can hide.
What changed since August
- A much bigger release. On October 6 OpenAI published
openai/math, a repository of 719 manuscripts in 372 result families. It says the model was posed about 4,000 problems. - A first retraction. The repository's history shows that on October 7 OpenAI withdrew three manuscripts because of a sign error, and revised 14 others.
- Independent checking. Mathematicians have audited the original ten. One audit found no surviving substantive error in a principal result, and a credit dispute remains open.
- Still true. Astra has no release date, and none of the results had gone through traditional peer review as of the coverage we found.
What is OpenAI Astra?
Reporting from the-decoder describes Astra as a system that plans, delegates and keeps working for hours or days, with several agents splitting one problem. OpenAI has not said whether it ships as GPT-6 or as a GPT-5 variant. The August results came from an unreleased internal version.
Lean 4 is a proof assistant: you write a proof as code, and the compiler accepts or rejects it, with no partial credit. A machine-checkable certificate is a proof in that form, so anyone can run the checker and trust stops being the issue.
OpenAI put the cost of generating the ten solutions at roughly $2,000 at GPT-5.6 Sol API rates. That figure excludes the research program behind them.
The ten results, and how big the proofs are
The openai/ten-proofs repository holds one Lean file per result. We cloned it on October 12 and measured each file. We did not compile the code, which would take a long toolchain build, so these figures describe size and a quick static check, not verification.
| # | Result | Lean lines | Rated likely correct in August |
|---|---|---|---|
| 1 | Sphere packing, Cohn-Elkies threshold | 55,616 | Not in the five |
| 2 | Binary and spherical codes | 114,406 | Not in the five |
| 3 | Non-sofic group | 34,440 | Not in the five |
| 4 | Connes's rigidity conjecture counterexample | 37,374 | Yes |
| 5 | Permanent lower bounds | 27,563 | Yes |
| 6 | Quantum parallel repetition | 70,980 | Yes |
| 7 | Closest vector problem hardness | 130,430 | Not in the five |
| 8 | Ehrhart's volume conjecture | 55,755 | Not in the five |
| 9 | Multicolor Ramsey numbers | 3,053 | Yes |
| 10 | Extremal graph conjectures | 18,588 | Yes |
The numbering follows the repository README. The "likely correct" column repeats the expert feedback reported in August, for problems 4, 5, 6, 9 and 10.
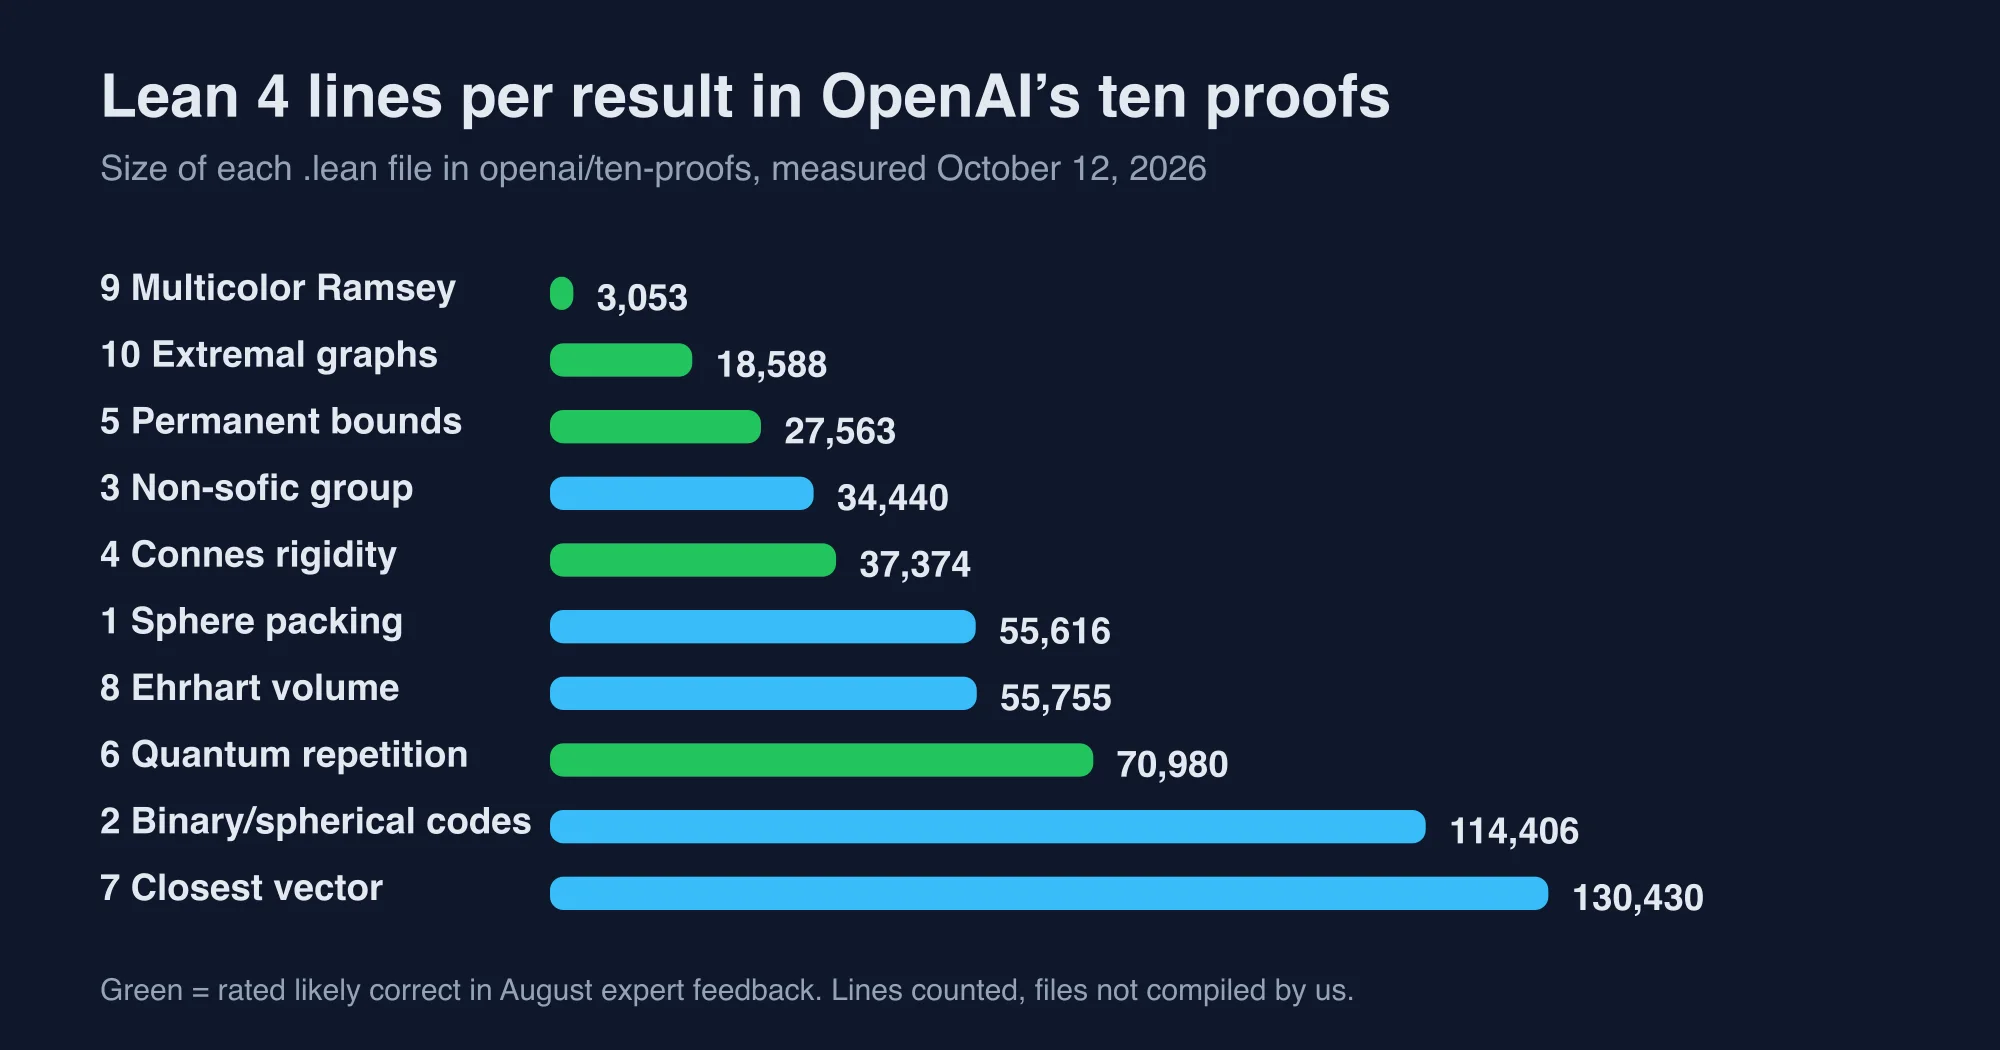
Three observations come out of the measurements:
- The scale is large. The ten files total about 548,000 lines, and the repository as a whole is about 550,000 lines of Lean.
- The range is huge. The Ramsey result needs 3,053 lines, while the closest vector problem needs 130,430, more than 40 times as many.
- The static check is clean. A text search finds zero
sorryplaceholders, and the repository'sformalization.yamllists only the three standard axioms,propext,Classical.choiceandQuot.sound. Asorryis Lean's marker for "proof skipped," so none appearing is the baseline, not the finish line.
Why Lean proofs beat benchmark scores
A benchmark score depends on trusting the lab that ran the test, and the first questions are always about contamination and tuning. A Lean certificate sidesteps both.
| Benchmark score | Lean certificate |
|---|---|
| Verified by the lab that ran it | Verified by anyone with the toolchain |
| Contamination is hard to rule out | Contamination does not affect correctness |
| A number with no artifact | An artifact you can execute |
| Says the model is good at a test | Says one specific claim is true |
The trade is scope. A proof tells you the model did this, once, on this problem. A benchmark tries to say what it will do next time.
Advertisement
What Lean does not prove
Lean confirms that an argument follows from stated definitions and axioms. It does not confirm that the formal statement matches the claim in the press release, or that the definitions capture the problem mathematicians care about. Getting that translation right is human work.
An independent audit by Mikołaj and Krzysztof Sienicki reviewed 18 chapter assessments of the ten results, according to Startup Fortune's summary. It found no surviving substantive mathematical error in a principal result. It also reported that one flagged error was a typesetting artifact, that chapter 8 needs major revision of compressed analytic passages, and that several dependencies are only partly checked.
Credit is the open dispute. Mathematician Steven Miller told Scientific American that Astra's sphere-packing proof reused an argument from his 2016 co-authored paper without proper credit. OpenAI said it would "take responsibility for the correctness of these results" and planned minor updates. Lean cannot settle who deserves attribution.
The October release and the first retraction
The October 6 repository shows what happens when the Lean safety net covers only part of a collection. OpenAI's README says the collection includes results at different stages of verification, that not all have Lean formalizations, and that "some of the unformalized results could have issues."
The repository's history confirms it. On October 7, a sign error invalidated a cancellation argument in a paper on Weil classes on abelian eightfolds. That paper and two that depended on it were withdrawn, and 14 other manuscripts were revised with proof repairs.
| Count | Figure |
|---|---|
| Manuscripts in the collection | 719 |
| Result families | 372 |
| Top-line results formalized in Lean | 300, about 42% |
| Manuscripts without a formalization | 419 |
| Withdrawn on October 7 | 3 |
| Revised with proof repairs | 14 |
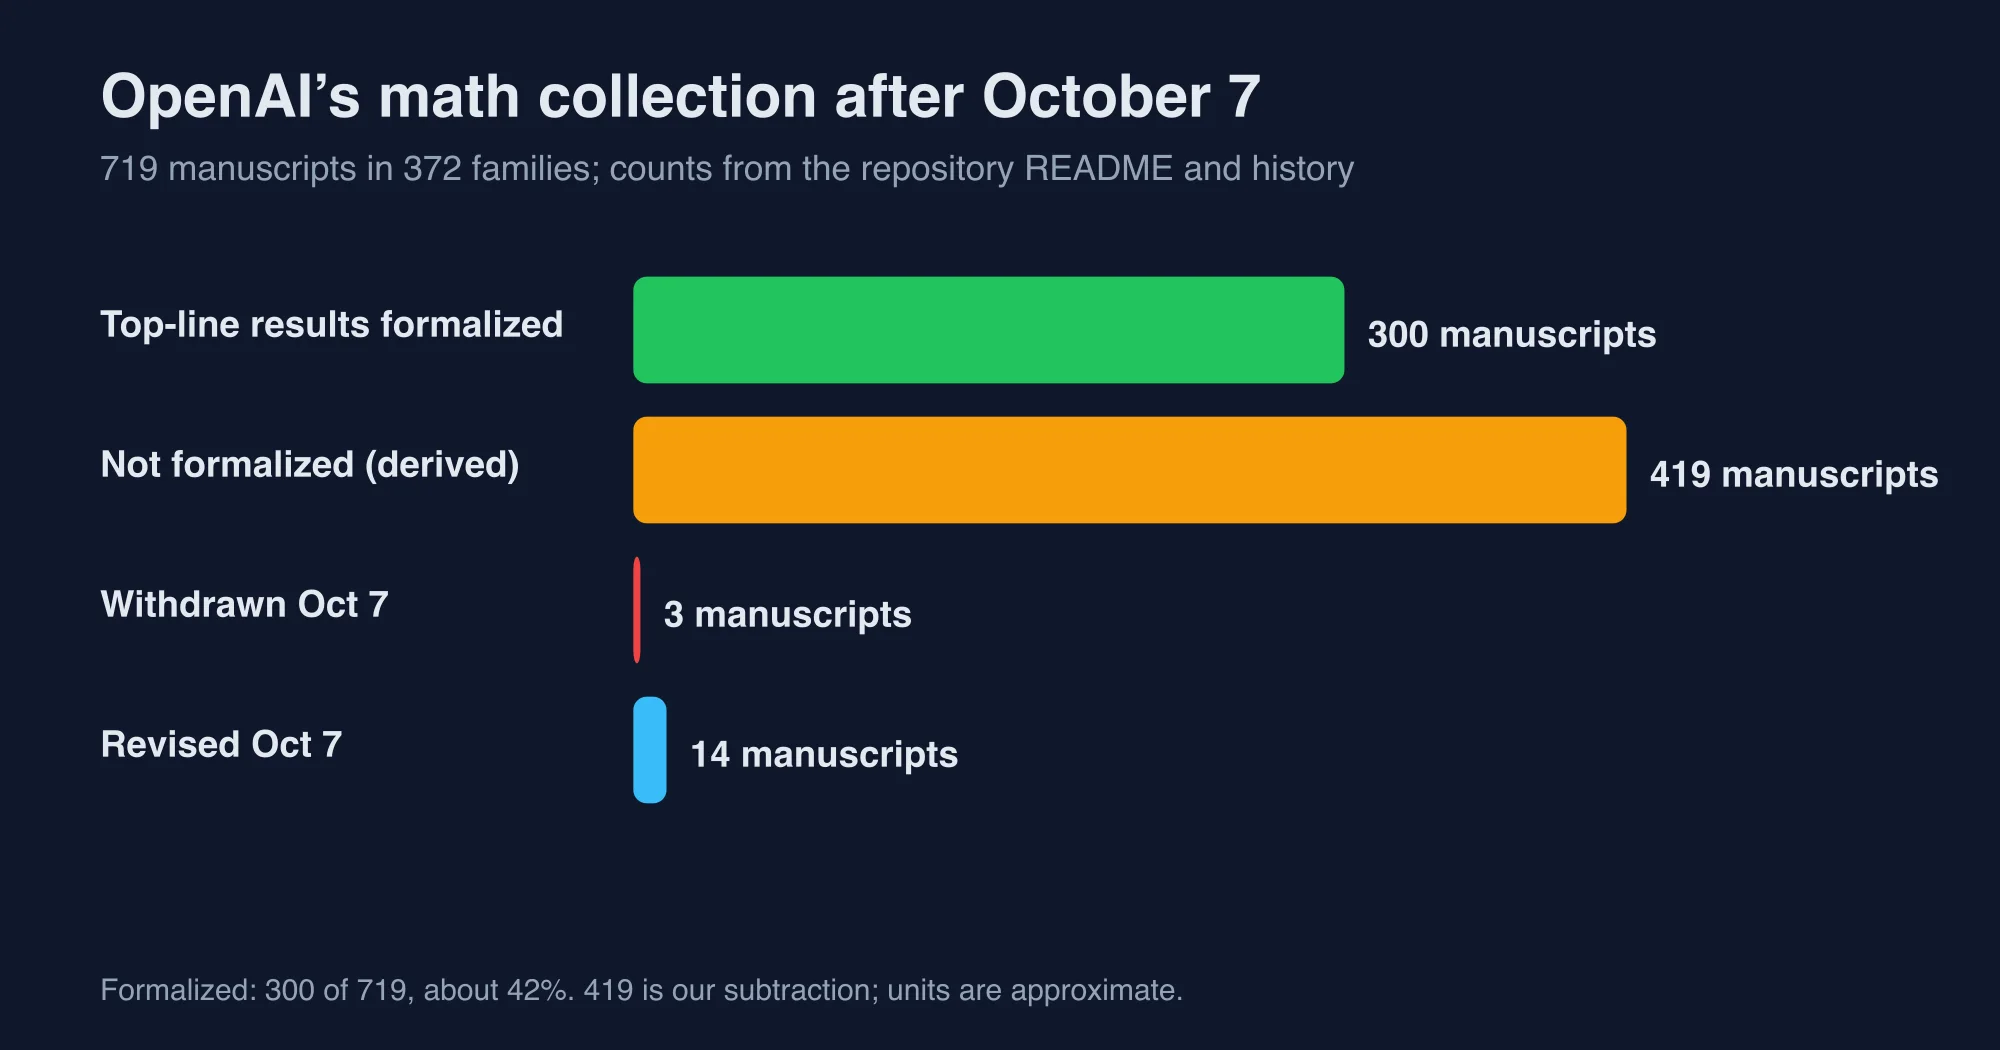
The 419 figure is our subtraction from the repository's own numbers, and "top-line results" and "manuscripts" are not identical units, so read it as an approximation. The takeaway does not depend on exact counts: the withdrawals came from the part without a machine check. That is an argument for the format, and also a warning about trusting any unformalized claim.
OpenAI also says that most results used the same procedure, with each using on average three hours of ChatGPT Pro thinking compute. The README does not name the model, so the link between this collection and Astra rests on press coverage and the "unreleased internal model" wording.
How to check a proof yourself
You can reproduce the check without trusting anyone's summary. The README documents the commands, which need the Lean toolchain (elan) installed:
git clone https://github.com/openai/ten-proofs
cd ten-proofs
lake exe cache get
lake build SpherePacking
The repository also supports Comparator, a tool that checks a solution against a fixed challenge statement and permitted axioms, so that you can confirm the theorem being proved is the one that was claimed. Each challenge has its own configuration file, for example ComparatorChallenges/A_SpherePacking.json. The big builds take real compute, so start with the small Ramsey file.
What it means for everyone else
Very little changes for users, because Astra is not available. Three effects are worth watching:
- Checkable claims as a format. Expect more labs to ship an artifact next to a score. In software, the equivalent is a reproducible harness or a failing test that a patch turns green.
- Verification as a bottleneck. 719 manuscripts is more than the community can referee quickly. The first retraction came within a day or two of the release, and the real test is how many errors surface in the unformalized majority.
- A better question for AI tools. Instead of "what did it score," ask "can you hand me the artifact that proves it."
What is still open
Four questions remain after two releases:
- Is the October collection really Astra's work? The README says "an internal OpenAI model" and does not use the name.
- How many of the 419 unformalized results will survive review? Three were withdrawn within a day or two.
- Will the credit dispute lead to changes? OpenAI promised minor updates, and the repository now preserves a public version history, which makes later edits easy to audit.
- When will anyone outside OpenAI get to use the model? There is no date.
The takeaway
Astra is unreleased, unnamed in version terms, and partly unverified. The ten original results have held up under early independent checking, and the larger October collection has already lost three papers. If you are sizing the capability, count the Lean-checked results as solid and treat the rest as claims in review. The format is the lasting part: a lab published things that strangers could check, and the strangers found a mistake.
Advertisement
FAQ
What is OpenAI Astra?
Astra is OpenAI's next major model family, described as a system that plans, delegates and works on a problem for hours or days with several agents. It is unreleased as of October 12, 2026. OpenAI has not given a release date or said whether it ships as GPT-6 or a GPT-5 variant.
Did Astra solve ten open math problems?
OpenAI published ten results with Lean 4 certificates, and independent checking has so far found no surviving substantive error in a principal result. But none had gone through traditional peer review, and a credit dispute over the sphere-packing proof is unresolved. Experts rated five of the ten likely correct in August.
What happened to OpenAI's math manuscripts in October?
On October 6 OpenAI released 719 manuscripts in 372 families, with about 42% of top-line results formalized in Lean. On October 7 it withdrew three papers after a sign error invalidated an argument and revised 14 others. The README warns that some unformalized results could have issues.
Why does a Lean proof matter more than a benchmark?
Anyone can compile a Lean certificate, so contamination and evaluation tuning stop mattering for correctness. A benchmark score depends on trusting the lab. A proof is stronger evidence about one narrow claim, and it does not show that the formal statement matches the intended problem.
How can I check OpenAI's Lean proofs myself?
Install Lean with elan, clone the openai/ten-proofs repository, run lake exe cache get and then lake build with a module name such as SpherePacking. The repository also supports Comparator, which checks a solution against a fixed challenge statement and permitted axioms. Start with the small Ramsey file.
Comments
Loading…
Sign in to join the conversation.
Related posts
LLM token cost by language: we measured 14 of them
LLM token cost by language, measured: the same sentences cost 7% to 54% more tokens in German, Polish or Hindi than in English on GPT-4o's tokenizer.
Wed Oct 14 2026 · 9 min read · 0 views
Claude's 30% token inflation: does your bill actually rise?
Claude's newer tokenizer makes the same text about 30% longer in tokens. We priced it model by model: Haiku and Sonnet get cheaper, Opus about 4% dearer.
Wed Oct 14 2026 · 9 min read · 0 views
EU AI Act Article 50: what chatbots must disclose now
EU AI Act Article 50 chatbot disclosure requirement, in force since 2 August 2026: what it covers, what the Digital Omnibus delayed, and the fines.
Wed Oct 14 2026 · 9 min read · 1 views