Claude Opus 5.5 returns 400 errors. Here is how to fix it
By Nihar Ranjan Das · Fri Sep 25 2026 · 8 min read · 0 views
View as a Web StoryAI#migration#claude opus 5.5#anthropic api#tool_choice#adaptive thinking
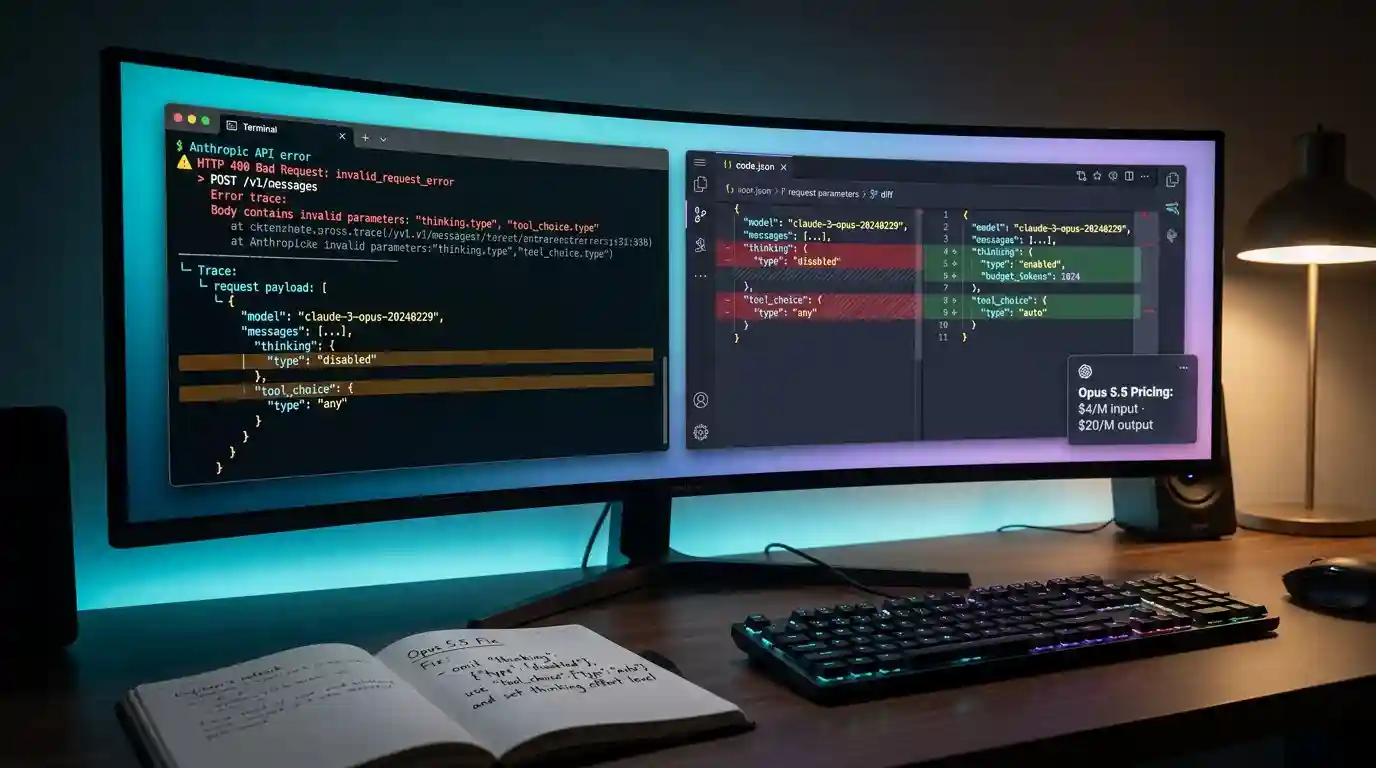
If your code moves from claude-opus-5 to claude-opus-5-5 and starts returning 400 errors, one of two request fields is the cause. Either thinking is set to disabled, or tool_choice is set to any or tool. Remove both, set an effort level, and the errors stop.
Claude Opus 5.5 is Anthropic's flagship model for long-running agentic coding and knowledge work, released September 22, 2026. According to Anthropic's pricing page, it costs $4 per million input tokens and $20 per million output tokens, down from $5 and $25 on Opus 5. That price cut only pays off if the migration does not break production first. TechCrunch's launch report covered the release, and 9to5Google noted that OpenAI launched GPT-6 Sol and Luna on the same day, so many teams are re-examining their model choices at once.
Four changes break code that already runs on Opus 5, according to the Opus 5.5 migration guide. A fifth changes behavior without any error at all. This post explains each of these changes in the order that most engineering teams are likely to encounter them during a real migration.
Why does Opus 5.5 return "thinking.type.disabled is not supported"?
Adaptive thinking is the mode where the model decides how much to reason on each turn, and on Opus 5.5 it is always on. Any request that turns thinking off returns a 400 invalid_request_error. On Opus 5, thinking: {"type": "disabled"} was accepted at effort high or below. On Opus 5.5 it is rejected, along with the manual thinking: {"type": "enabled", "budget_tokens": N} form.
The two error messages that developers will encounter, quoted from Anthropic's Opus 5.5 release notes, read:
"thinking.type.disabled" is not supported for this model. Use "thinking.type.adaptive" and "output_config.effort" to control thinking behavior."thinking.type.enabled" is not supported for this model. Use "thinking.type.adaptive" and "output_config.effort" to control thinking behavior.The fix is to delete the thinking field, as the thinking documentation describes, or send {"type": "adaptive"}, which Anthropic says is equivalent. Then use the effort parameter, which sets how much the model thinks and spends on a request, to control depth, latency, and cost. See the effort guide for the levels. Where you once disabled thinking to save money, lower the effort instead.
One side effect matters for parsing. Every response can now begin with one or more thinking blocks. At the default display of omitted, their thinking field comes back empty. Select content blocks by their type, never by position, and pass thinking blocks back unmodified in tool-use loops.
Why does Opus 5.5 reject tool_choice any and tool?
Opus 5.5 does not support forced tool use, so tool_choice set to {"type": "any"} or {"type": "tool", "name": "..."} returns a 400. The error text, per Anthropic, is:
tool_choice: type "tool" and "any" are not supported for this model.Only the {"type": "auto"} and {"type": "none"} settings are currently supported by this model. The same validation applies to the token counting endpoint, which means that a cost estimation script that previously worked on Opus 5 can unexpectedly fail as well.
Anthropic gives two replacements. Strict tool use is a setting that forces a tool call's input to match its schema, and it replaces forcing for schema-valid JSON. Keep tool_choice on auto and set strict: true on the tool, as the strict tool use guide explains. You can also move the schema to structured outputs. If you forced a tool so the model would act instead of chatting, say in the prompt when the tool applies.
Advertisement
Here is the before and after for a typical extraction call. The first version works on claude-opus-5 and returns a 400 on claude-opus-5-5:
client.messages.create(
    model="claude-opus-5",
    thinking={"type": "disabled"},
    tool_choice={"type": "tool", "name": "extract_invoice"},
    ...
)

client.messages.create(
    model="claude-opus-5-5",
    tool_choice={"type": "auto"},
    output_config={"effort": "low"},
    tools=[{"name": "extract_invoice", "strict": True, ...}],
    ...
)
If an agent of yours loops or stalls around tool selection, our post on why your agent loops forever and toolChoice explains the older failure pattern. Opus 5.5 removes the setting that caused it.
What happens to thinking blocks when you switch models?
A thinking block is a response block that carries the model's reasoning, and it is now tied to the model that produced them and to the conversation they came from. Opus 5.5 reads blocks from Opus 5 and earlier Opus, Sonnet, and Haiku models. It does not read blocks from Claude Fable or Claude Mythos models.
The table below summarizes what Anthropic documents for moves involving Opus 5.5:
| Conversation moves | Reasoning kept? |
|---|---|
| Opus 5 to Opus 5.5 | Yes |
| Opus 5.5 to Fable 5.1 or Mythos 5.1 (Claude API) | Yes |
| Opus 5.5 to any other model | No, later turns run without it |
| Fable or Mythos to Opus 5.5 | No |
When a block cannot be read, the API drops it before the model sees it. The request succeeds, and dropped blocks are not billed.
A second rule can produce a 400. The API checks whether the system prompt, the tools, or an earlier message changed after a thinking block was produced. For accounts created on or after August 31, 2026, 00:00 UTC, that check is enforced by default. A request that replays a block after such a change returns a 400.
The safest habit, per the preserved thinking guide, is to keep conversations append-only. To change instructions or tools mid-conversation, use mid-conversation system messages instead of editing earlier content. Prompt caching benefits from the same habit, which our post on agent memory that does not wreck your prompt cache covers in detail.
What breaks if you use computer use?
On the Claude API and Google Cloud, Opus 5.5 no longer accepts the computer_20251124 tool. A request that declares it returns a 400 that begins 'claude-opus-5-5' does not support tool types: computer_20251124.
The fix is to drop the computer-use-2025-11-24 beta header and declare {"type": "computer_toolset_20260801"} in tools. Your agent loop also has to handle member tool_use blocks, batch actions, and a toolset_name on results.
Amazon Bedrock is the exception. According to Anthropic, computer_20251124 keeps working on Opus 5.5 there, so Bedrock users need no change. Integrations already on the toolset, and the browser use tool, need no change either.
What fails silently on Opus 5.5?
Text between tool calls now arrives in thinking blocks, and at the default display setting those blocks are empty. An app that streams "I'm checking the database now" style progress updates to users will go quiet between tool calls. No error appears.
The migration guide's note on tool-call text says to set thinking.display to a value that returns the text. If your interface shows progress between tool calls, test it before you ship. Unit tests that only check for a 200 response will pass while the product feels frozen.
A related change also shows up without any code edit. The default effort on Opus 5.5 is medium, where Opus 5 ran at high. A request that omits effort will therefore behave differently and cost differently. Set effort explicitly and re-run your evaluation sweep. Anthropic also notes the model tends to think more per turn at the same setting, most of all at xhigh and max, so leave room in max_tokens.
What does the price cut actually save?
Opus 5.5 lowers every price line by a fifth or more. The figures below come from Anthropic's pricing notes for the model.
| Price line (per million tokens) | Opus 5 | Opus 5.5 |
|---|---|---|
| Input | $5 | $4 |
| Output | $25 | $20 |
| Cache read | $0.50 | $0.20 |
The cache read drop, from $0.50 to $0.20, is the biggest change in percentage terms. Agent workloads that reread a long prefix on every turn gain the most. Our earlier breakdown of how Bedrock cache writes ate 85 percent of one AI bill shows why cache lines matter more than headline rates.
Migrating costs engineering time, and because the default effort level changed underneath your existing requests, the resulting bill can move in either direction depending on how your particular workload behaves. Consider a team spending $10,000 a month: a 20 percent list cut is $2,000 only if quality and token counts hold. Measure a week of real traffic at a fixed effort before you decide the cut is a saving.
Should you upgrade now or wait?
Upgrade now if your production code already runs Opus 5 with thinking switched on and leaves tool_choice at its auto default, because Anthropic says code in that state needs no change beyond the model identifier itself. Wait, or test first, if you disabled thinking, forced a tool, use computer use on the Claude API or Google Cloud, or stream progress text to users.
Follow this order:
- Change the model ID to
claude-opus-5-5in a staging environment. - Remove
thinkingsettings and choose aneffortlevel. - Replace
tool_choicetypesanyandtoolwithautoplus strict tool use. - Move computer use to the toolset if you are on the Claude API or Google Cloud.
- Set
thinking.displayif users see text between tool calls. - Re-run your evaluation set and compare cost and quality.
Our earlier post on why Claude Opus 5 returns 400 on temperature covers a similar class of rejected parameters. The pattern is consistent. Anthropic is removing knobs that fought the model's own reasoning, and each removal shows up first as a 400.
Advertisement
FAQ
How do I fix "tool_choice: type tool and any are not supported for this model"?
Set `tool_choice` to `{"type": "auto"}`, or remove it. Add `strict: true` to the tool for schema-valid input, or use structured outputs. If the model must call a tool, state in the prompt when that tool applies. Opus 5.5 supports only `auto` and `none`.
Can I turn thinking off on Claude Opus 5.5?
No. Adaptive thinking is always on. Sending `thinking: {"type": "disabled"}` returns a 400. Omit the field, or send `{"type": "adaptive"}`, and use the `effort` parameter to lower thinking depth, latency, and cost.
What is the default effort on Claude Opus 5.5?
The default is `medium`. Claude Opus 5 ran at `high` when effort was omitted. Set `effort` explicitly and re-run your evaluations, because both quality and cost can shift when the default changes.
Does Opus 5.5 read thinking blocks from other models?
It reads blocks from Opus 5 and earlier Opus, Sonnet, and Haiku models. It does not read blocks from Fable or Mythos models. Unreadable blocks are dropped before the model sees them, the request still succeeds, and dropped blocks are not billed.
How much does Claude Opus 5.5 cost?
Opus 5.5 costs $4 per million input tokens and $20 per million output tokens. Cache reads cost $0.20 per million tokens. Batch processing is half price, at $2 input and $10 output, according to Anthropic's documentation. Opus 5.5 also adds new safeguard categories, such as a biology classifier, so handle `stop_reason: "refusal"` as the [refusals guide](https://platform.claude.com/docs/en/build-with-claude/refusals-and-fallback) describes.
Comments
Loading…
Sign in to join the conversation.
Related posts
GPT-6 Sol vs Opus 5.5: cost per correct task, not per token
GPT-6 Sol costs exactly half as much per token as Claude Opus 5.5, but that does not make it half the cost of finishing your work. Sol is cheaper per attempt. Opus 5.5 succeeds more often on hard
Fri Sep 25 2026 · 6 min read · 0 views
Sora 2's API is gone. What replaces it?
OpenAI removed the Sora 2 Videos API on Sept 24, 2026 with no successor. Compare per-second prices for Veo 3.1, Kling and self-hosted options.
Thu Sep 24 2026 · 5 min read · 2 views

GPT-6 Astra Pricing: The 272K-Token Cost Cliff
GPT-6 Astra API pricing is $10 per million input tokens, but a prompt over 272K tokens reprices the whole request to $20. Here is the real cost, and how it compares.
Sun Sep 06 2026 · 6 min read · 3 views