The cheapest AI API is not the cheapest to run
By Nihar Ranjan Das · Sat Aug 08 2026 · 7 min read · 4 views · Updated Wed Oct 14 2026
View as a Web StoryAI#ai#developer tools#ai api pricing#deepseek#llm costs#reasoning models#prompt caching
Every comparison chart ranks AI APIs by price per million tokens. That number does not tell you what a task costs. A model with a lower list price can finish a job for more money than a pricier one, because it may write ten times as many tokens getting there.
Two things from our August version of this post have flipped. DeepSeek's "significant increase" arrived, but as a peak-and-off-peak rate card, not a flat rise. And Anthropic cancelled the price rise it had scheduled for Claude Sonnet 5. The core argument survives, and the numbers below are current as of October 14, 2026.
Why price per token misleads you
Price per token is what a provider charges for text going in and coming out, quoted per million tokens. It is easy to compare, which is why every pricing table uses it. It is also only half of a cost calculation.
The other half is how many tokens the model spends. That is a property of the model, not the price list.
A reasoning model generates intermediate reasoning text before its final answer. You pay for that text at the output rate, even if you never display it. A published study of reasoning-model token overhead, cited in the August version of this post, put the overhead between 3.11 times and 14.78 times the tokens of non-reasoning models on the same benchmarks. I did not re-check the study this week.
The overhead is also badly distributed. The study found the overspend concentrates on easy problems, where extra reasoning changes nothing. Some models burned over 900 tokens answering a trivial arithmetic question.
What the current prices are
Prices below are USD per million tokens, from DeepSeek's pricing page and Anthropic's pricing page.
| Model | Input | Cache-hit input | Output |
|---|---|---|---|
| DeepSeek V4.1 Flash, off-peak | $0.15 | $0.003 | $0.60 |
| DeepSeek V4.1 Flash, peak | $0.30 | $0.006 | $1.20 |
| DeepSeek V4 Pro, off-peak | $0.66 | $0.022 | $1.98 |
| DeepSeek V4 Pro, peak | $1.32 | $0.044 | $3.96 |
| Claude Haiku 5.5 (prompts up to 100k tokens) | $0.10 | $0.01 | $0.50 |
| Claude Haiku 5.5 (prompts over 100k tokens) | $0.50 | $0.05 | $2.50 |
| Claude Sonnet 5.5 | $2.00 | $0.10 | $10.00 |
| Claude Sonnet 5 | $2.00 | $0.20 | $10.00 |
| Claude Sonnet 4.6 | $3.00 | $0.30 | $15.00 |
Three things moved since August.
- DeepSeek restructured its rates. Off-peak prices are half of peak. Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays, excluding Chinese public holidays. Flash output went from $0.28 to $0.60 off-peak and $1.20 at peak, so the warned-about increase did happen. The pricing page no longer carries the earlier notice, and it still says DeepSeek "reserves the right to adjust" prices.
- Claude Sonnet 5 stays at $2 and $10. The $3 and $15 rate scheduled for September 1 "will not occur," according to Anthropic's pricing page. The introductory price is now the standard price.
- Claude Haiku 5.5 is the new low anchor. At $0.10 input and $0.50 output, it undercuts DeepSeek's Flash list price at both peak and off-peak, for prompts up to 100,000 tokens.
That last point breaks the August framing. "DeepSeek is the cheapest" was the assumption behind most budget charts. On list price it no longer is.
A worked example: the same task, five ways
List prices do not decide the bill. Tokens and caching do. Here is one illustrative task, with my own assumptions, not a benchmark:
Advertisement
- 20,000 input tokens, of which 18,000 hit the cache and 2,000 are fresh.
- 1,500 output tokens for a model that answers directly.
- 15,000 output tokens for a model that reasons at ten times the volume, inside the 3.11 to 14.78 range above.
| Setup | Cost per task |
|---|---|
| Haiku 5.5, direct answer | $0.00113 |
| DeepSeek Flash off-peak, direct answer | $0.00125 |
| DeepSeek Flash peak, direct answer | $0.00251 |
| Sonnet 5.5, direct answer | $0.0208 |
| DeepSeek Flash peak, 10x reasoning tokens | $0.0187 |
| DeepSeek Flash off-peak, 10x reasoning tokens | $0.00935 |
| Haiku 5.5, 10x reasoning tokens | $0.00788 |
Read the fifth row against the fourth. A model with a 1/8th list price on output ends up within 10% of Sonnet 5.5's cost per task, purely because it spends ten times the tokens. If the cheaper model also fails more often, the cheaper bill is not cheaper.
The same table shows why model choice is not the only lever. Hitting the cache cut every input bill above by more than half. Peak versus off-peak moved DeepSeek's cost by 2x with no change in quality.
The number almost no chart shows you
Prompt caching is the largest single lever, and it is not a model choice. It is a billing mechanism where a provider charges less for input tokens it has already processed and stored.
Most applications send a large, stable prefix on every call: a system prompt, tool definitions, retrieved documents, conversation history. That prefix caches well.
The size of the discount varies by provider, and no pricing table makes this obvious:
- DeepSeek Flash: $0.15 down to $0.003 off-peak, a 50x reduction.
- Claude Sonnet 5.5: $2.00 down to $0.10, a 20x reduction.
- Claude Haiku 5.5: $0.10 down to $0.01, a 10x reduction.
Two teams on the same model can see input bills that differ by an order of magnitude, based only on whether their prompts are stable enough to hit the cache. Put fixed content at the front, unchanged between calls. That is usually a bigger win than switching providers.
This is also why agent workloads get expensive fast. An agent re-sends its accumulated context on every step. Our look at whether AI agents can run a business is a cost story as much as a competence story. Steps multiply tokens, and tokens multiply everything else.
One Haiku 5.5 trap deserves a warning for agent builders. A request whose prompt passes 100,000 tokens pays the higher rate on all of it, including cache reads. A long-running agent can cross that line mid-task and quintuple its input price.
Price changes are a planning risk
Both big moves this quarter show why a fixed budget needs headroom at both ends. DeepSeek raised effective prices through a new rate card. Anthropic held a price it had said would rise. Neither was predictable from a pricing table in August.
If you plan next quarter's inference budget against today's numbers, add a buffer, and design so you can swap the model behind a thin interface. The open-weights route is the usual hedge. It is less available than it looks, and self-hosting swaps a token bill for a GPU bill, which only wins at high, steady utilisation.
What to measure instead
Stop comparing price per million tokens. Measure cost per completed task. Artificial Analysis defines cost per task as input, cached and output prices multiplied by tokens consumed, and notes that models producing longer answers or more reasoning tokens "will have a higher cost per task, even at identical per-token prices."
The procedure for your own workload is short.
- Take 50 real requests from your application, not benchmark prompts.
- Run them through each candidate model.
- Record total input tokens, total output tokens, and how many outputs were acceptable.
- Divide total dollar cost by the number of acceptable outputs.
The last step is the one people skip. A model that costs half as much per token and fails twice as often costs the same per usable result.
Three adjustments to run alongside it:
- Check your cache hit rate before you check anyone's price list.
- Cap reasoning effort where the provider exposes the control. Much of the overhead is spent on easy inputs.
- Use batch processing for work that can wait. Anthropic discounts input and output by 50% on its Batch API, which beats most model downgrades without changing quality. DeepSeek's off-peak rate gives a similar 50% for flexible timing.
So which API should you use?
For most production workloads, per-token price should be about the fourth thing you consider. Choose on task success rate first, then on cache behaviour with your prompt shape, then on whether the provider's data terms fit your product, then on price.
Budget-tier models earn their place in narrow, high-volume, low-ambiguity jobs: classification, extraction, routing, short summaries. Reasoning overhead stays small there and failure is cheap to detect. Frontier models remain better economics wherever a wrong answer costs real money, or where a retry loop can quietly triple the tokens you budgeted.
Advertisement
FAQ
Which AI API is cheapest in 2026?
On list price, Claude Haiku 5.5 at $0.10 input and $0.50 output undercuts DeepSeek V4.1 Flash. Real cost depends on tokens used, cache hits and task success rate.
Why do reasoning models cost more per task?
They generate hidden reasoning text billed at the output rate. A study cited in this post put the overhead at 3.11x to 14.78x versus non-reasoning models.
How much does prompt caching save?
It depends on provider: DeepSeek Flash cache hits cost 50x less than misses, Claude Sonnet 5.5 20x less, Claude Haiku 5.5 10x less.
Did DeepSeek raise its prices?
Effectively yes. Its rate card now has peak and off-peak prices, and Flash output is $0.60 off-peak and $1.20 at peak, up from $0.28 in August.
How do I compare models fairly?
Run 50 real requests per model, record tokens and acceptable outputs, then divide total cost by acceptable outputs.
Comments
Loading…
Sign in to join the conversation.
Related posts
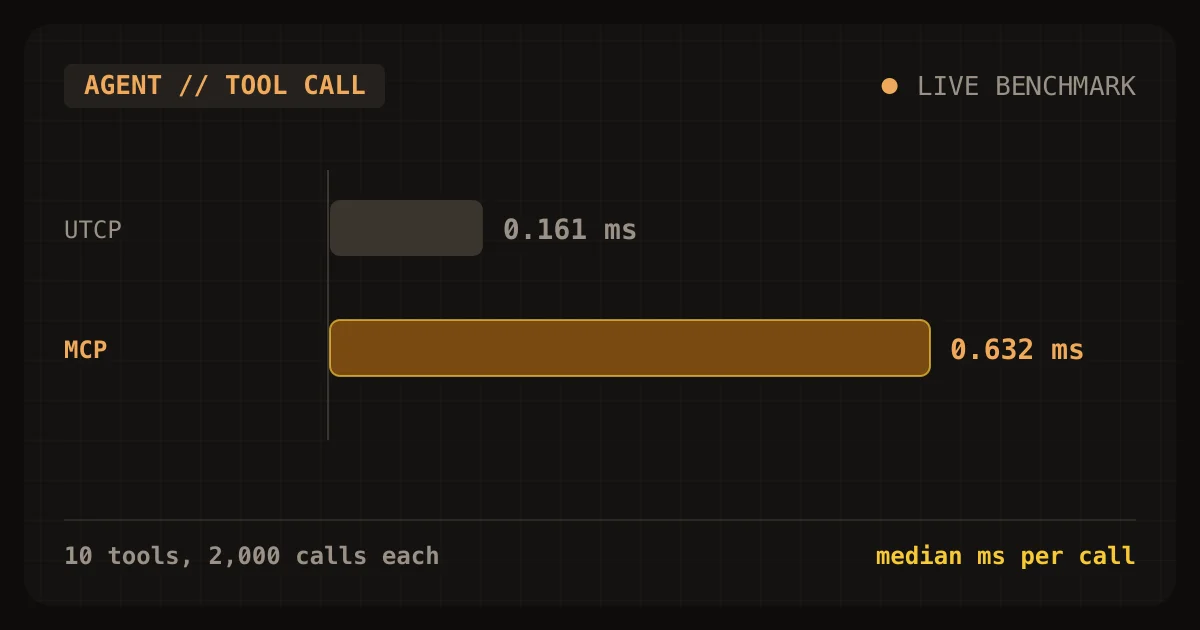
MCP vs UTCP: we timed both on the same 10 tools
On identical tools, a UTCP call took 0.161 ms and an MCP call 0.632 ms. Tool definition size was nearly the same. Here is how to choose.
Wed Nov 04 2026 · 10 min read · 7 views
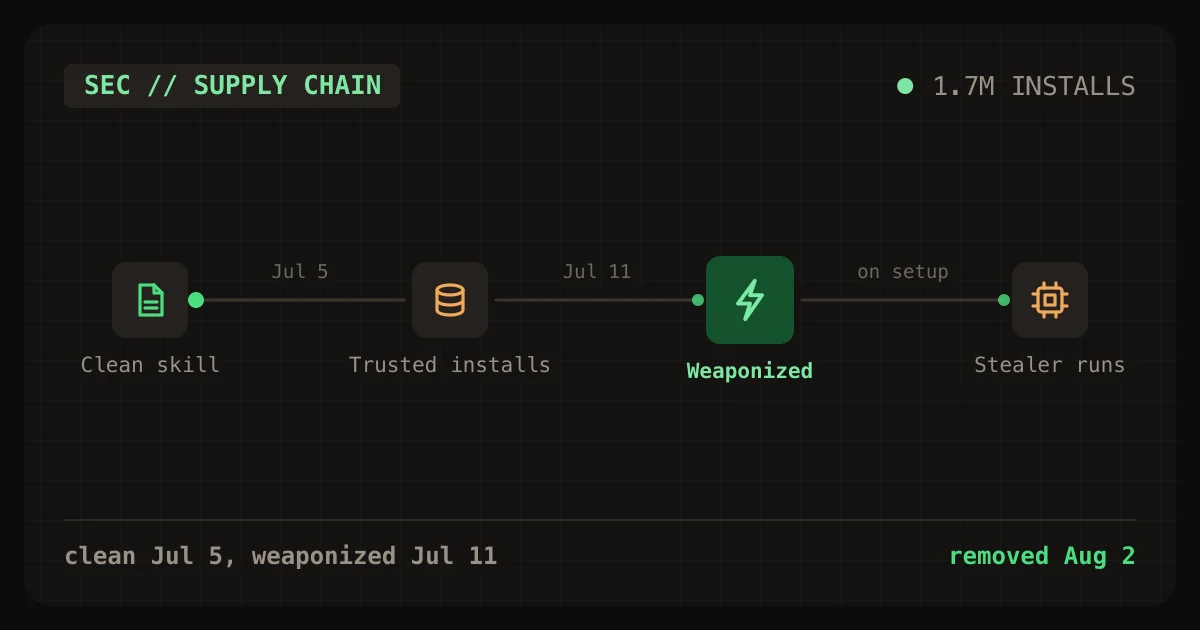
Are agent skills safe to install? A 1.7M-install trojan
Trojanized skills hit 1.7M displayed installs before takedown. See how the attack worked, a 6-check audit script, and what it found on a real dev machine.
Wed Oct 28 2026 · 9 min read · 1 views
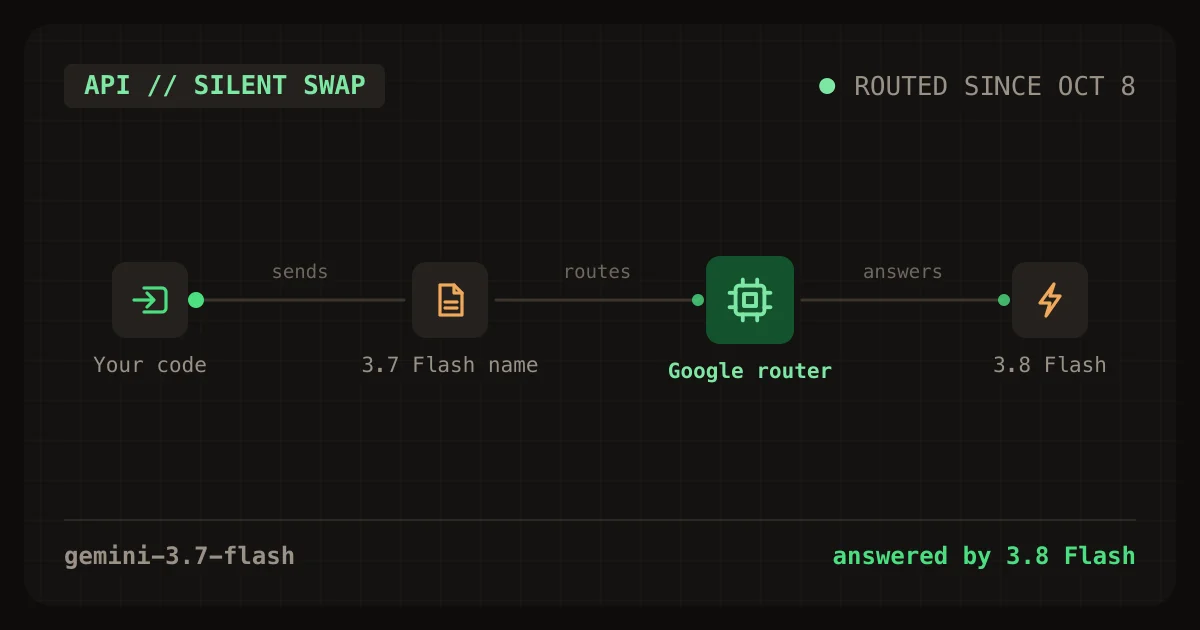
Gemini 3.7 Flash now runs as 3.8 Flash: what to check
Google quietly routes gemini-3.7-flash calls to 3.8 Flash. Check your logs, the minimal thinking error, and the Jan 1, 2027 price doubling. Scanner and test included.
Wed Oct 28 2026 · 9 min read · 2 views