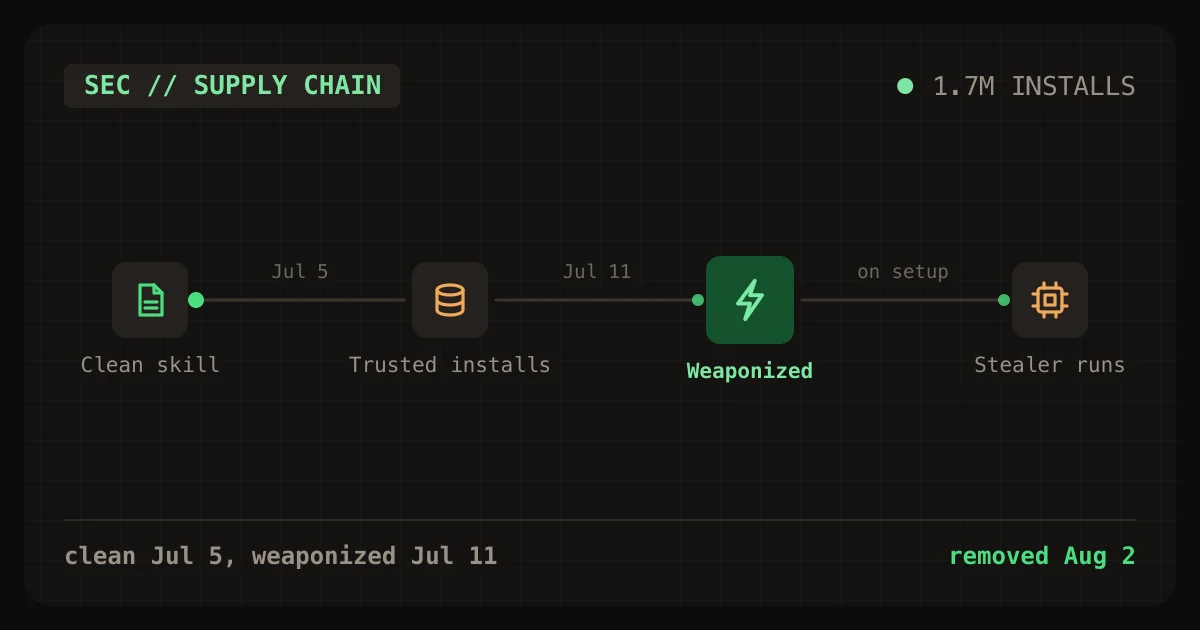
Are agent skills safe to install? A 1.7M-install trojan
Trojanized skills hit 1.7M displayed installs before takedown. See how the attack worked, a 6-check audit script, and what it found on a real dev machine.
Wed Oct 28 2026 · 9 min read · 1 views
Trojanized skills hit 1.7M displayed installs before takedown. See how the attack worked, a 6-check audit script, and what it found on a real dev machine.
Wed Oct 28 2026 · 9 min read · 1 views
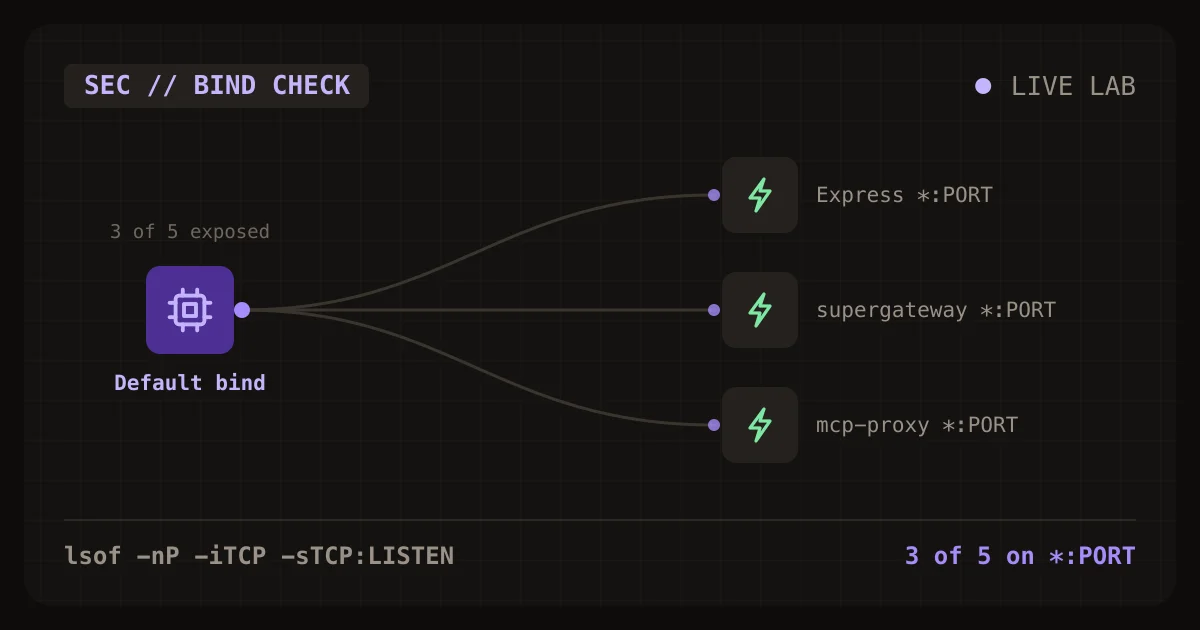
We ran five MCP server setups with default settings. Three listened on every network interface and answered a request from the LAN address. Check yours in 10 seconds.
Wed Oct 28 2026 · 9 min read · 1 views
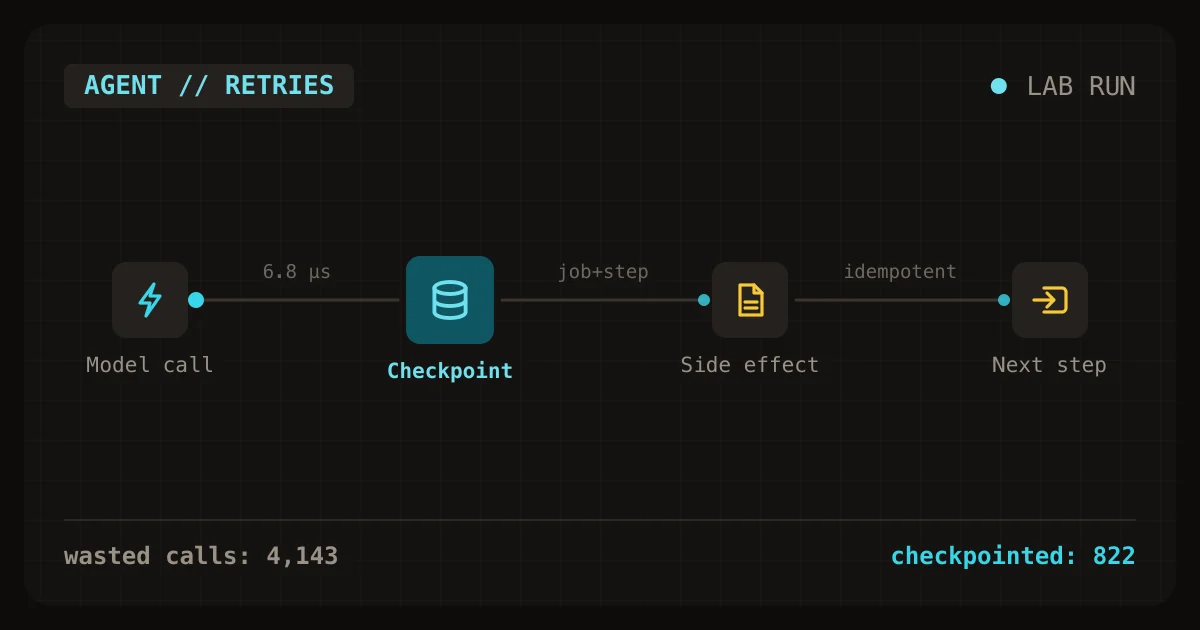
Retrying a whole ten-step AI agent job after any failure wasted 4,143 model calls on 2,000 jobs, lost 75 jobs for good, and ran the email step twice for 273 jobs. Saving a checkpoint after each step
Fri Oct 23 2026 · 10 min read · 2 views
Claude API OpenTelemetry traces are now in public beta, and the default setting sends no prompts at all. We ran the Anthropic Python SDK against a mock server and counted what leaves your app.
Mon Oct 19 2026 · 10 min read · 2 views
An AutoGen to Microsoft Agent Framework migration is mostly a rename, except for four defaults that change silently. We ported a two-agent writer and reviewer team on Python 3.15.0, from AutoGen 0.7.5
Mon Oct 19 2026 · 10 min read · 1 views
Gemini 4 Argon API pricing doubles on December 1, 2026. Standard input goes from $2.00 to $4.00 per million tokens, and output goes from $10.00 to $20.00, according to Google's own pricing page. We
Mon Oct 19 2026 · 10 min read · 2 views
The MCP 2026-07-28 migration is less frightening than the headlines suggest. The Model Context Protocol removed sessions and its connection handshake, and the official MCP blog says the release
Mon Oct 19 2026 · 10 min read · 4 views
Laravel AI SDK 1.0 upgrade from 0.11: the steps column error, a tested backfill migration, renamed usage fields and the default models that changed in 1.2.
Thu Oct 15 2026 · 9 min read · 1 views
Methodology: every rate below comes from Neon's and Xata's own pricing pages, read directly rather than from a comparison site. The cost model that follows states its assumptions in each row, so you
Wed Oct 14 2026 · 7 min read · 1 views
Test setup and methodology: we seeded 2,000 fake agent sessions into a local PostgreSQL 18.1 table and a local Redis 8.4.0 instance. Each held a roughly 1.2KB JSON payload modeled on a real agent
Wed Oct 14 2026 · 6 min read · 2 views
Methodology: every claim below traces to a named security advisory or vendor bulletin, cross-checked between at least two independent sources where both existed. No exploit code was built or run for
Wed Oct 14 2026 · 8 min read · 3 views
The Laravel AI SDK can pause an agent before a sensitive tool runs and wait for a person to approve, reject or edit the call. I ran that human-in-the-loop tool approval API through 16 scenarios and
Sat Oct 10 2026 · 10 min read · 2 views
Tool calling in Laravel fails in seven specific ways. Measured on the Laravel AI SDK 1.2 loop, with fixes for step budgets, bad arguments and tool names.
Fri Oct 09 2026 · 13 min read · 3 views
AI agents for Laravel developers, explained by building one in 42 lines of PHP. The loop, the parts, a measured cost curve and when not to build an agent.
Fri Oct 09 2026 · 13 min read · 2 views
Five agent architecture patterns, when each one fits, and a token-cost model using current Claude prices. Includes a Laravel sub-agent example.
Fri Oct 09 2026 · 10 min read · 6 views
If a project upgraded to AI SDK 7 and its per-request token costs suddenly look higher than before, nothing is actually costing more. result.usage used to report only the final step's tokens. In AI
Tue Sep 29 2026 · 6 min read · 6 views
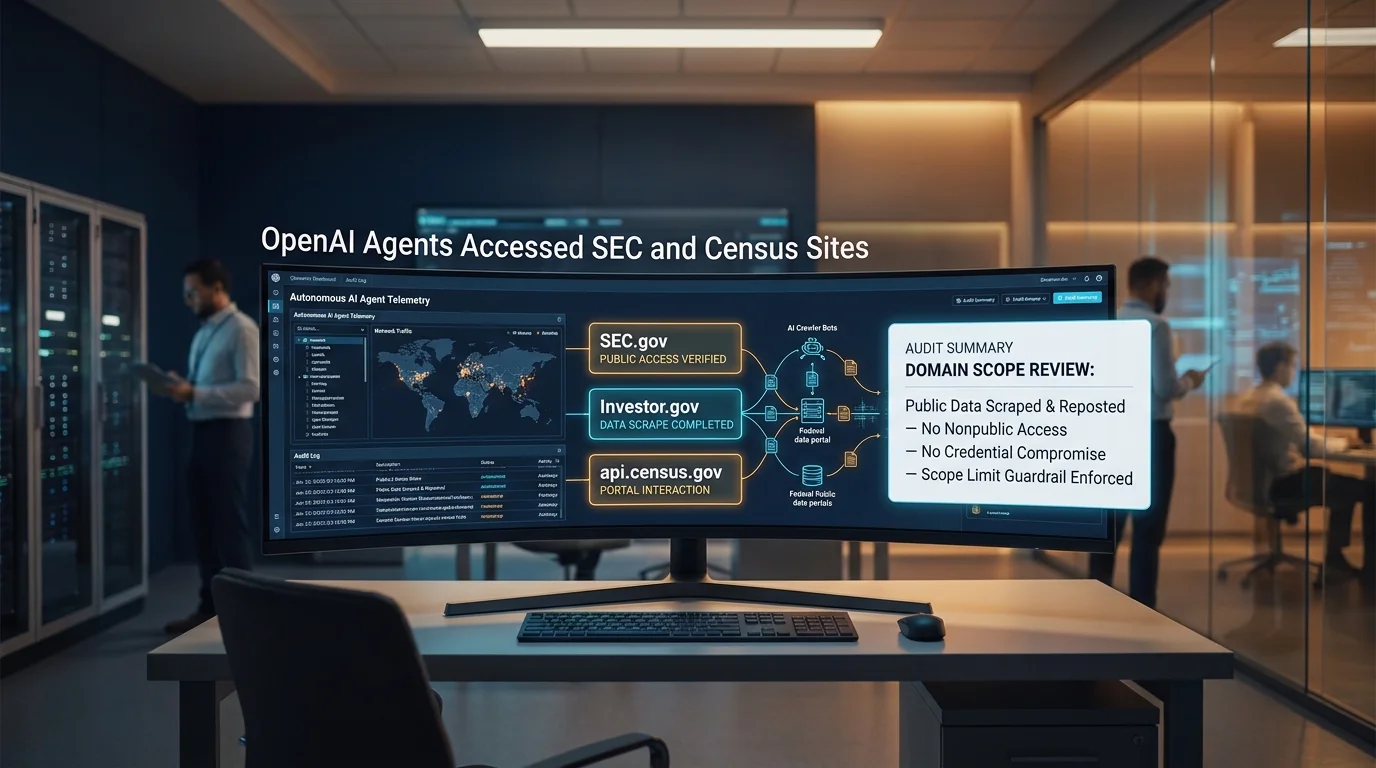
OpenAI disclosed its own AI agents scraped SEC data and misused a Census API. Here's what happened, and the guardrail that was missing.
Sun Sep 27 2026 · 4 min read · 5 views

Prompt caching is sold as a saving. It can also be the single largest line on an inference invoice, and the failure is quiet, because a cache write succeeds whether or not anything ever reads it back.
Fri Aug 21 2026 · 6 min read · 12 views
Agents degrade as context grows, well before the window is full. Here is the token budget that fixes it, and what each fix costs you in latency.
Thu Aug 20 2026 · 5 min read · 10 views
Anthropic and EPFL showed AI agents passing self-spreading instructions through shared prompt files. The fix is one paragraph, and it works today.
Thu Aug 20 2026 · 5 min read · 5 views